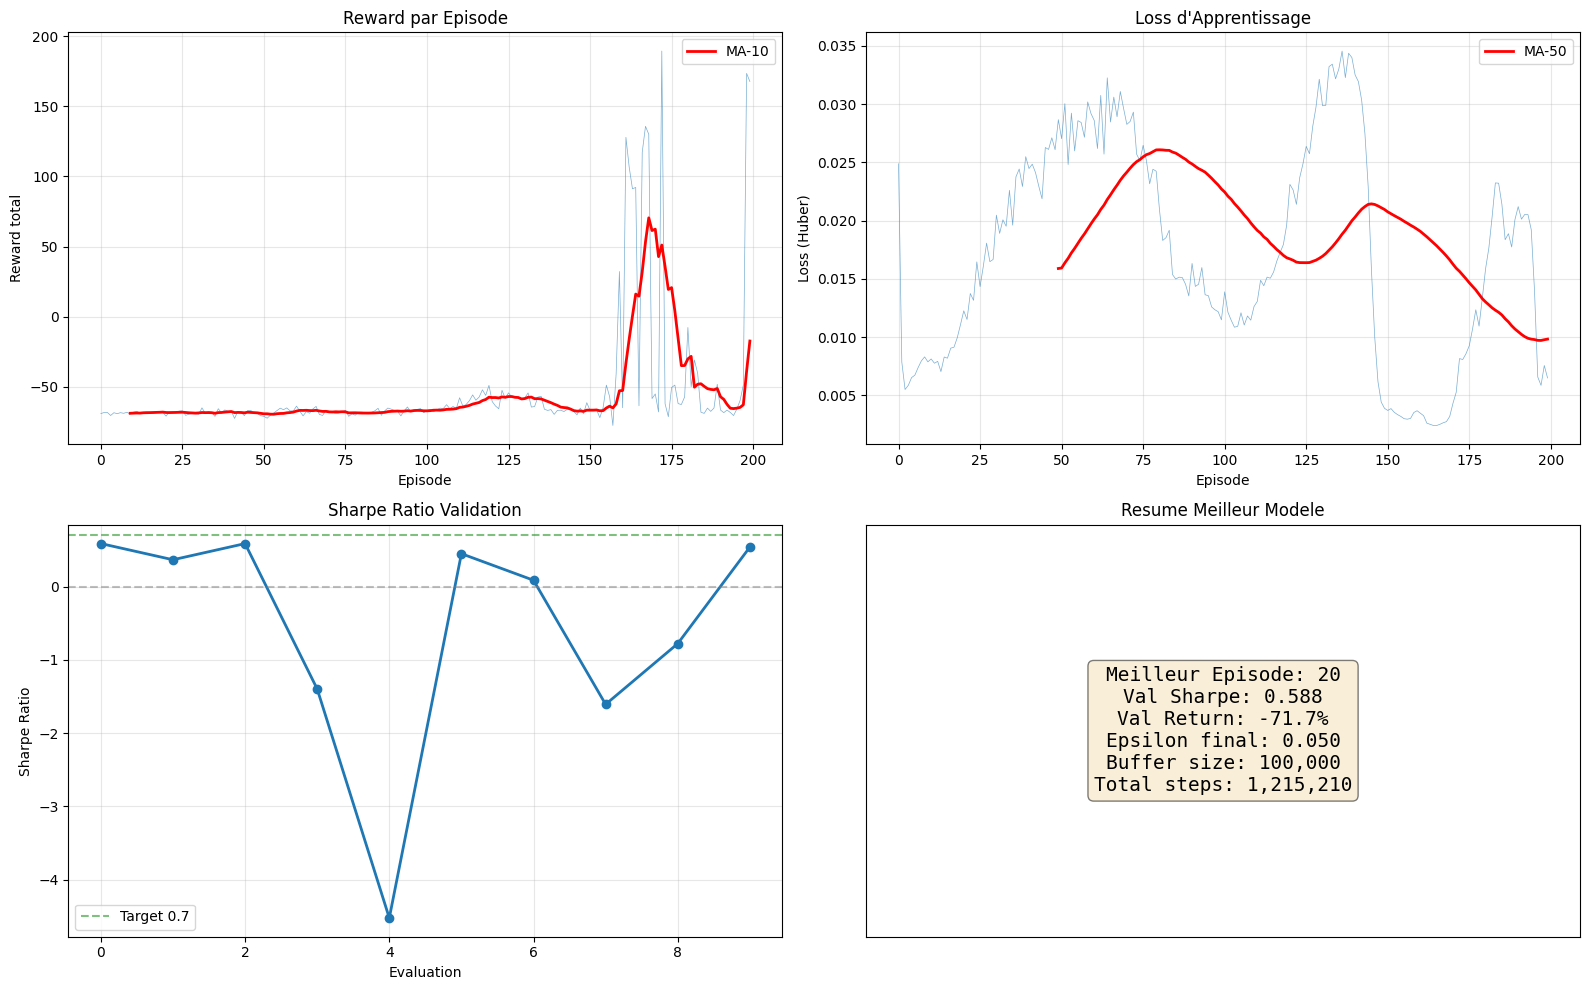
# Visualisation de l'entrainement
fig, axes = plt.subplots(2, 2, figsize=(16, 10))

axes[0, 0].plot(episode_rewards, alpha=0.6, linewidth=0.5)
axes[0, 0].plot(pd.Series(episode_rewards).rolling(10).mean(), color="red", linewidth=2, label="MA-10")
axes[0, 0].set_xlabel("Episode")
axes[0, 0].set_ylabel("Reward total")
axes[0, 0].set_title("Reward par Episode")
axes[0, 0].legend()
axes[0, 0].grid(True, alpha=0.3)

axes[0, 1].plot(losses, alpha=0.6, linewidth=0.5)
axes[0, 1].plot(pd.Series(losses).rolling(50).mean(), color="red", linewidth=2, label="MA-50")
axes[0, 1].set_xlabel("Episode")
axes[0, 1].set_ylabel("Loss (Huber)")
axes[0, 1].set_title("Loss d'Apprentissage")
axes[0, 1].legend()
axes[0, 1].grid(True, alpha=0.3)

axes[1, 0].plot(eval_sharpes, marker="o", linewidth=2)
axes[1, 0].axhline(0, color="gray", linestyle="--", alpha=0.5)
axes[1, 0].axhline(0.7, color="green", linestyle="--", alpha=0.5, label="Target 0.7")
axes[1, 0].set_xlabel("Evaluation")
axes[1, 0].set_ylabel("Sharpe Ratio")
axes[1, 0].set_title("Sharpe Ratio Validation")
axes[1, 0].legend()
axes[1, 0].grid(True, alpha=0.3)

checkpoint = torch.load("best_dqn_model.pt", weights_only=False)
axes[1, 1].text(0.5, 0.5,
    f"Meilleur Episode: {checkpoint['episode']}\n"
    f"Val Sharpe: {checkpoint['val_sharpe']:.3f}\n"
    f"Val Return: {checkpoint['val_return']:+.1f}%\n"
    f"Epsilon final: {agent.epsilon:.3f}\n"
    f"Buffer size: {len(agent.buffer):,}\n"
    f"Total steps: {agent.total_steps:,}",
    transform=axes[1, 1].transAxes, fontsize=14, verticalalignment="center",
    horizontalalignment="center", family="monospace",
    bbox=dict(boxstyle="round", facecolor="wheat", alpha=0.5))
axes[1, 1].set_title("Resume Meilleur Modele")
axes[1, 1].set_xticks([])
axes[1, 1].set_yticks([])

plt.tight_layout()
plt.savefig("dqn_training_curves.png", dpi=150, bbox_inches="tight")
plt.show()
print("Courbes sauvegardees dans dqn_training_curves.png")